


English · 简体中文 · 繁體中文 · 日本語 · 한국어 · Español · Français · Deutsch · Português · Italiano · Русский · हिन्दी · فارسی · Nederlands · Dansk · Svenska · Norsk
Agentic observability — one open-source platform for uptime, incidents, on-call, status pages, logs, traces, metrics & APM.
When things go wrong, be the first to know — and the fastest to fix.
OneUptime replaces a whole shelf of SaaS tools with one platform you can self-host for free. It catches the outage, pages the right person, updates your status page, finds the root cause, and even opens the fix PR.
Website • Docs • Quick Start • Pricing • Contribute
OneUptime brings monitoring, alerting, incident response, and observability into a single open-source app — so you stop paying for (and stitching together) a dozen separate tools.
| Instead of… | Use OneUptime for… |
|---|---|
| Pingdom / UptimeRobot | Uptime Monitoring — website, API, ping, port, SSL, DNS & synthetic checks from around the world |
| StatusPage.io | Status Pages — branded public & private status pages with subscribers |
| PagerDuty / Opsgenie | On-Call & Alerts — schedules, escalation policies, SMS / call / push / Slack |
| Incident.io | Incident Management — declare, triage, communicate, and post-mortem |
| Datadog / New Relic | APM & Metrics — traces, dashboards, and service performance |
| Loggly | Log Management — collect, search, and alert on logs |
| Sentry | Error Tracking — exceptions with full stack traces and context |
All of it is open source (Apache 2.0) and free to self-host in the Community Edition.
🌙 One incident, handled end to end
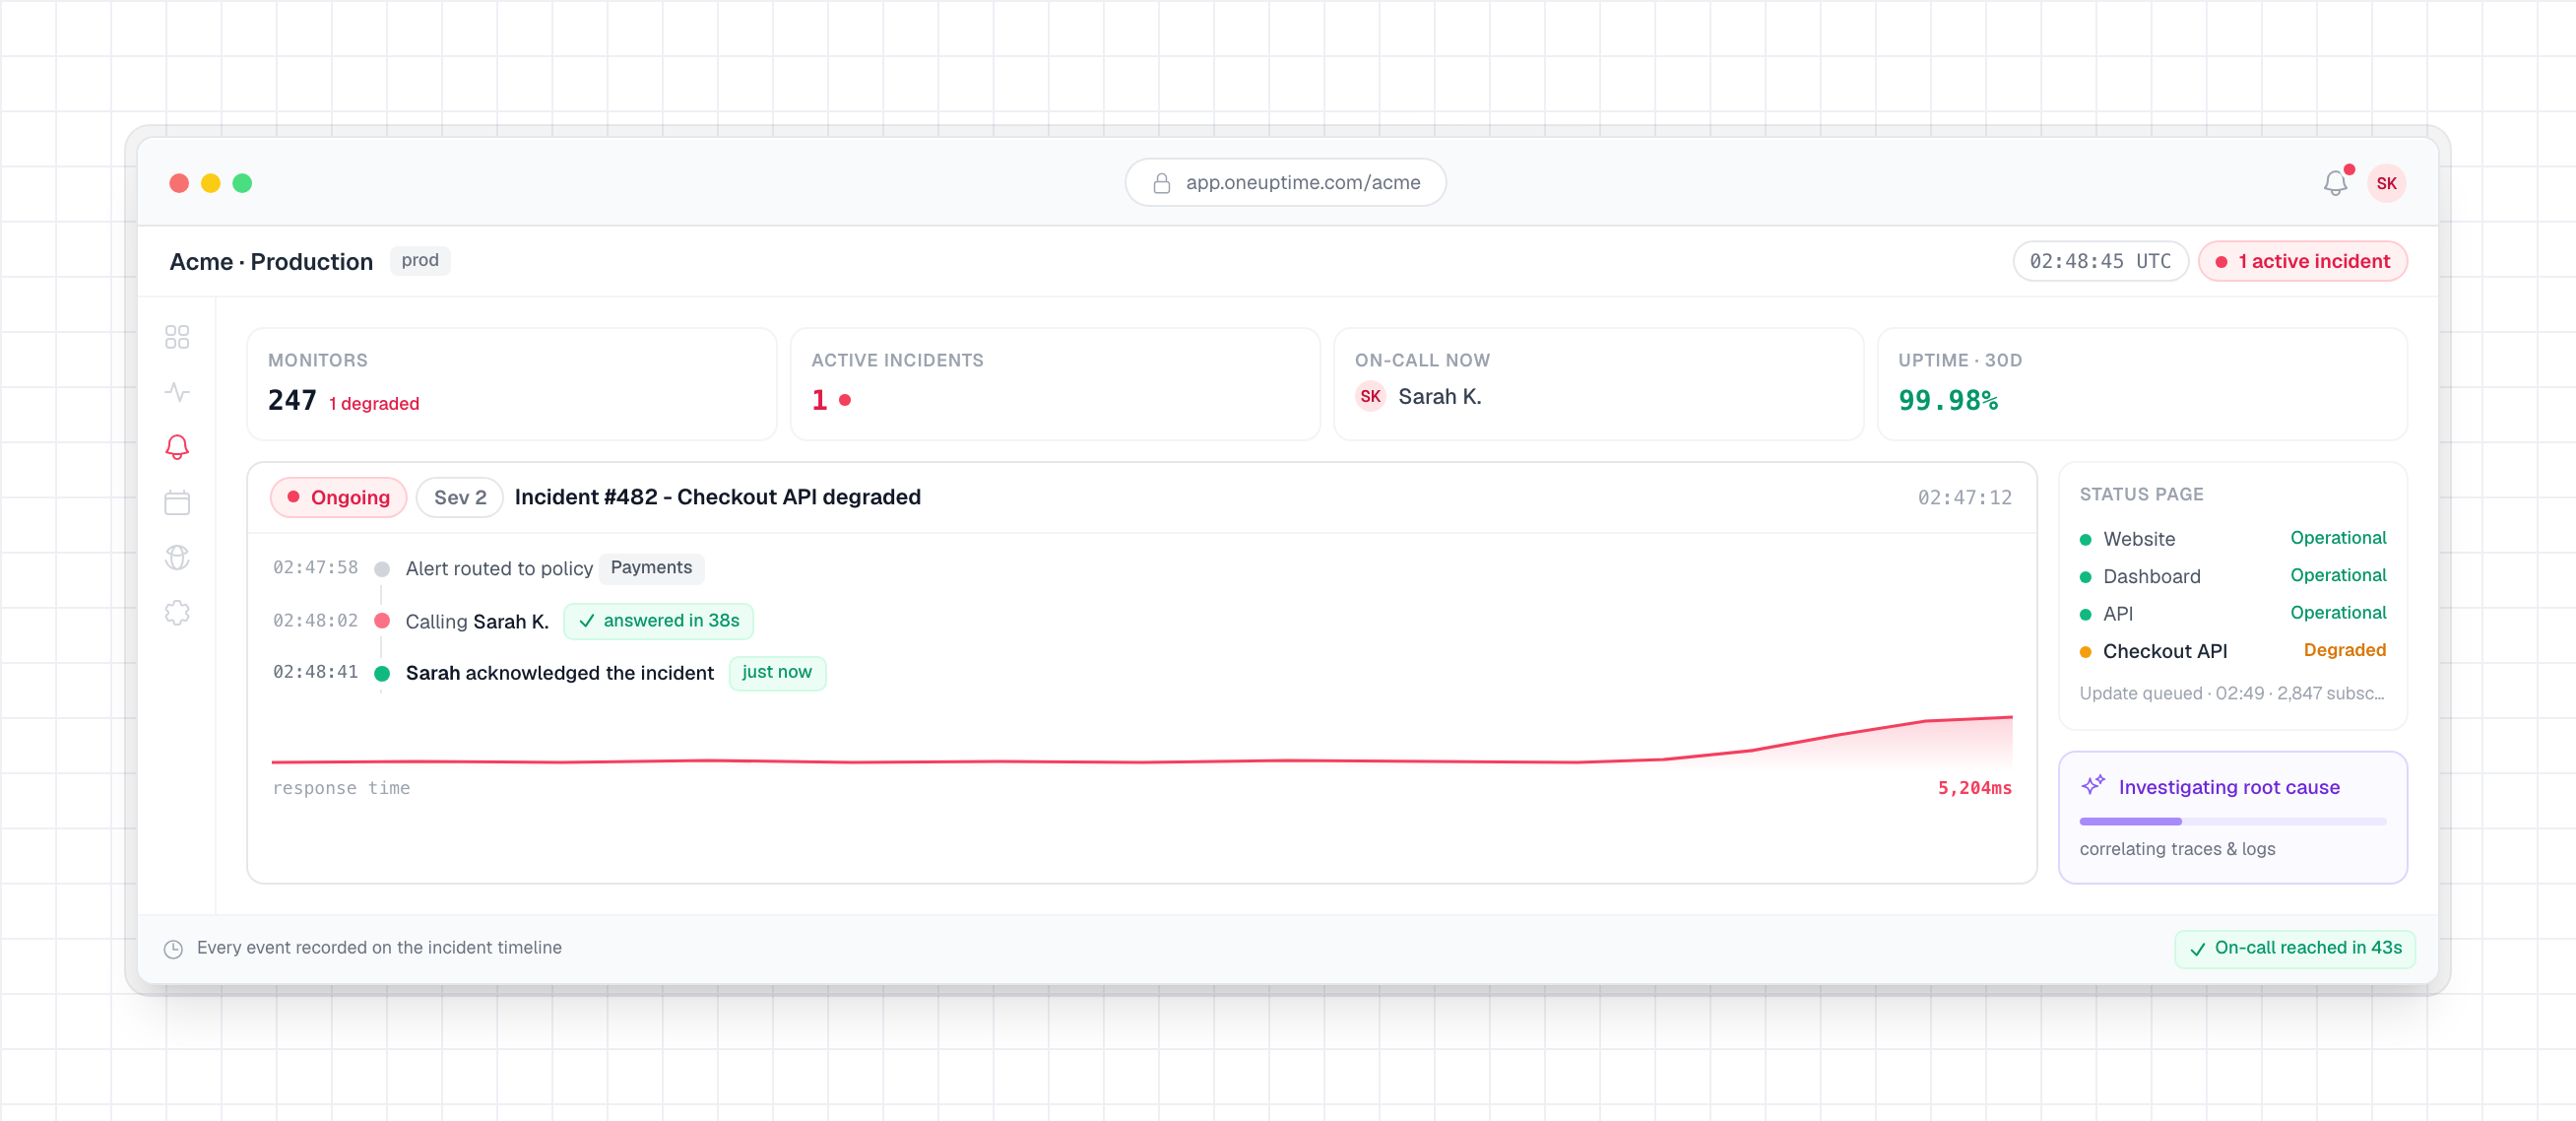
It's 2:47 AM. Checkout starts timing out. Here's what OneUptime does before most tools would even fire the first alert — and what the screenshots below actually show.
Probes in multiple regions catch checkout latency blowing past your 5s threshold and open an incident automatically — before your customers hit refresh.