


An open-source document parsing model with SOTA accuracy and speed, using an RSI loop during post-training.
Turn documents into Agent-Friendly data.
English · 简体中文
OXR (Optical Everything Recognition) is an open-source model from the SoMark team. It turns PDFs and document images into Agent-Friendly data in Markdown or JSON, with layout coordinates included.
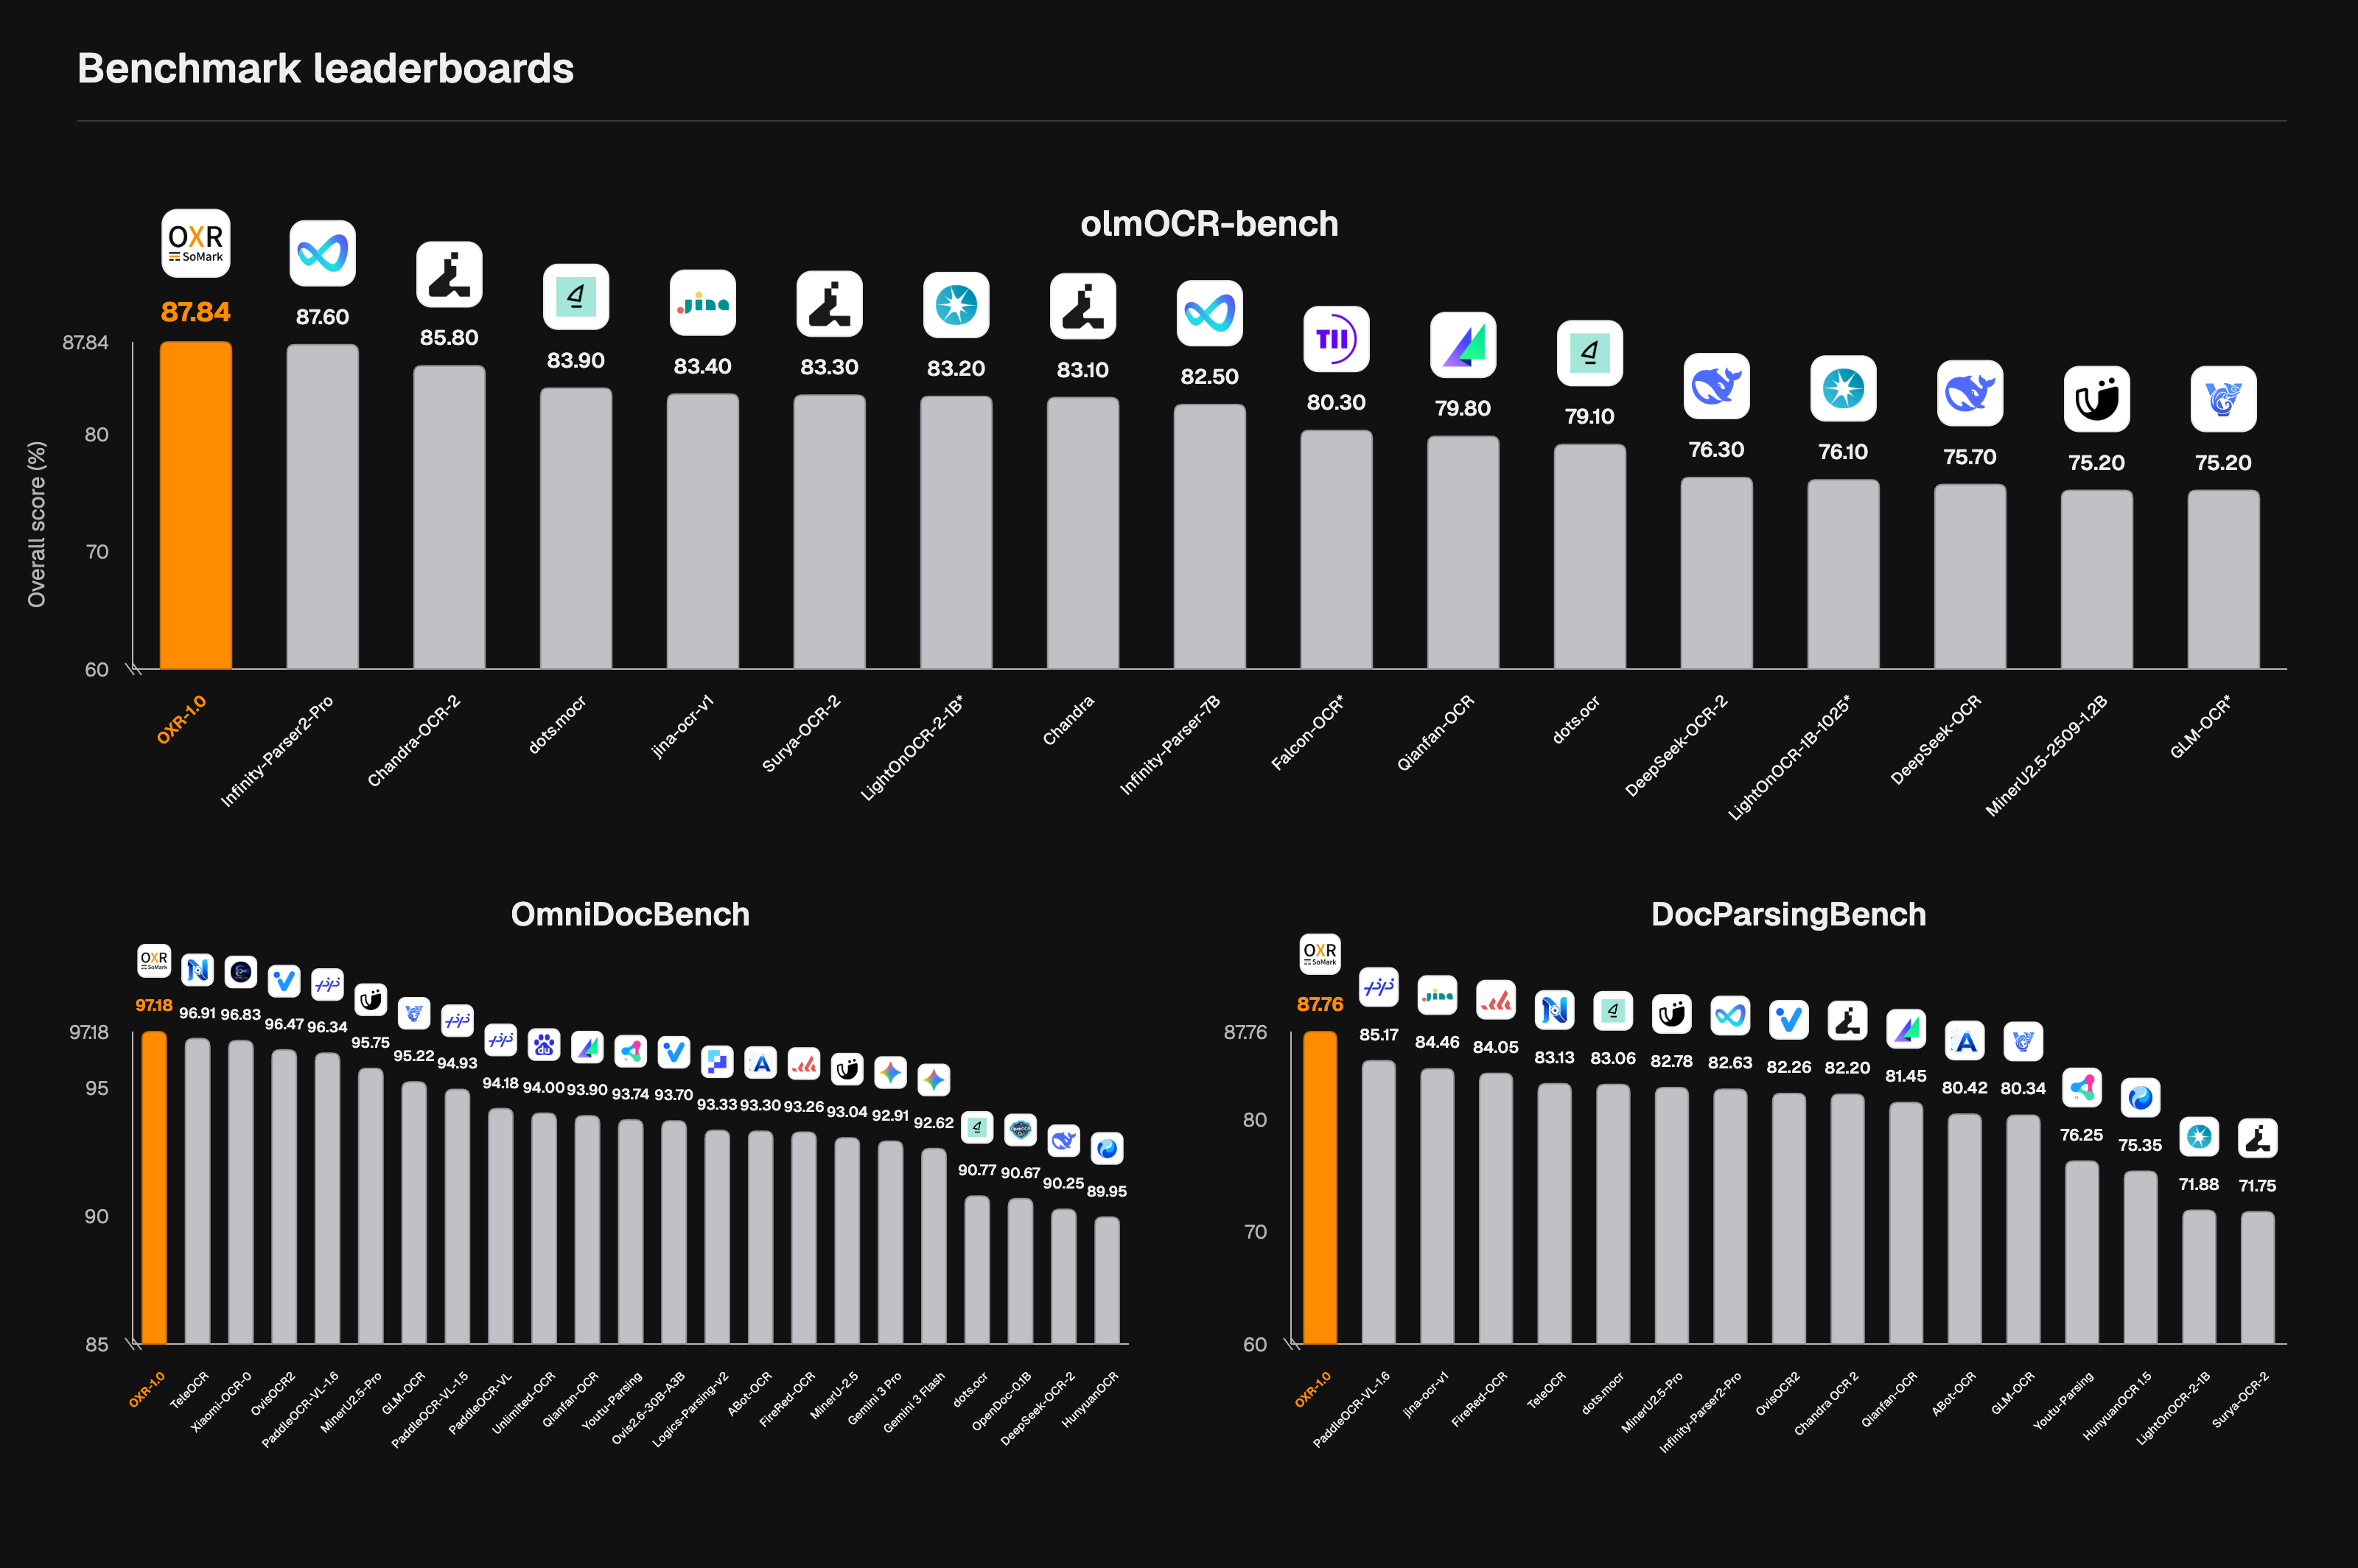
Pretrained from scratch, OXR uses a recursive self-improvement (RSI) loop during post-training—a first in document parsing. With just 1.3B parameters, OXR ranks #1 on olmOCR-Bench, OmniDocBench, and DocParsingBench while delivering industry-leading parsing speed.
OXR is the first to make its layout analysis module independent and pluggable. This design accelerates parsing and supports replacing the built-in layout model with a custom one. OXR continues to handle content recognition and reading order, enabling adaptation across diverse scenarios with minimal integration effort.
If this project helps you, please click ⭐ Star in the top-right corner to support us. It's the best encouragement you can give the developers!
-
🎯 SOTA Accuracy. #1 Across Three Benchmarks.
- OXR ranks 🏆#1 on olmOCR-Bench, OmniDocBench, and DocParsingBench, with a particularly wide lead in table parsing.
- OXR can recognize 13 document element types, from formulas and tables to chemical equations, chemical structures, and code blocks, with bounding box coordinates included. It also performs well on challenging documents and layouts, including A3 exam papers, newspapers, vertical text, and handwriting.
- See docs/benchmark.md for the full results and instructions to reproduce the evaluations.
-
🚀 1.3B Parameters. Top-Tier Parsing Speed.
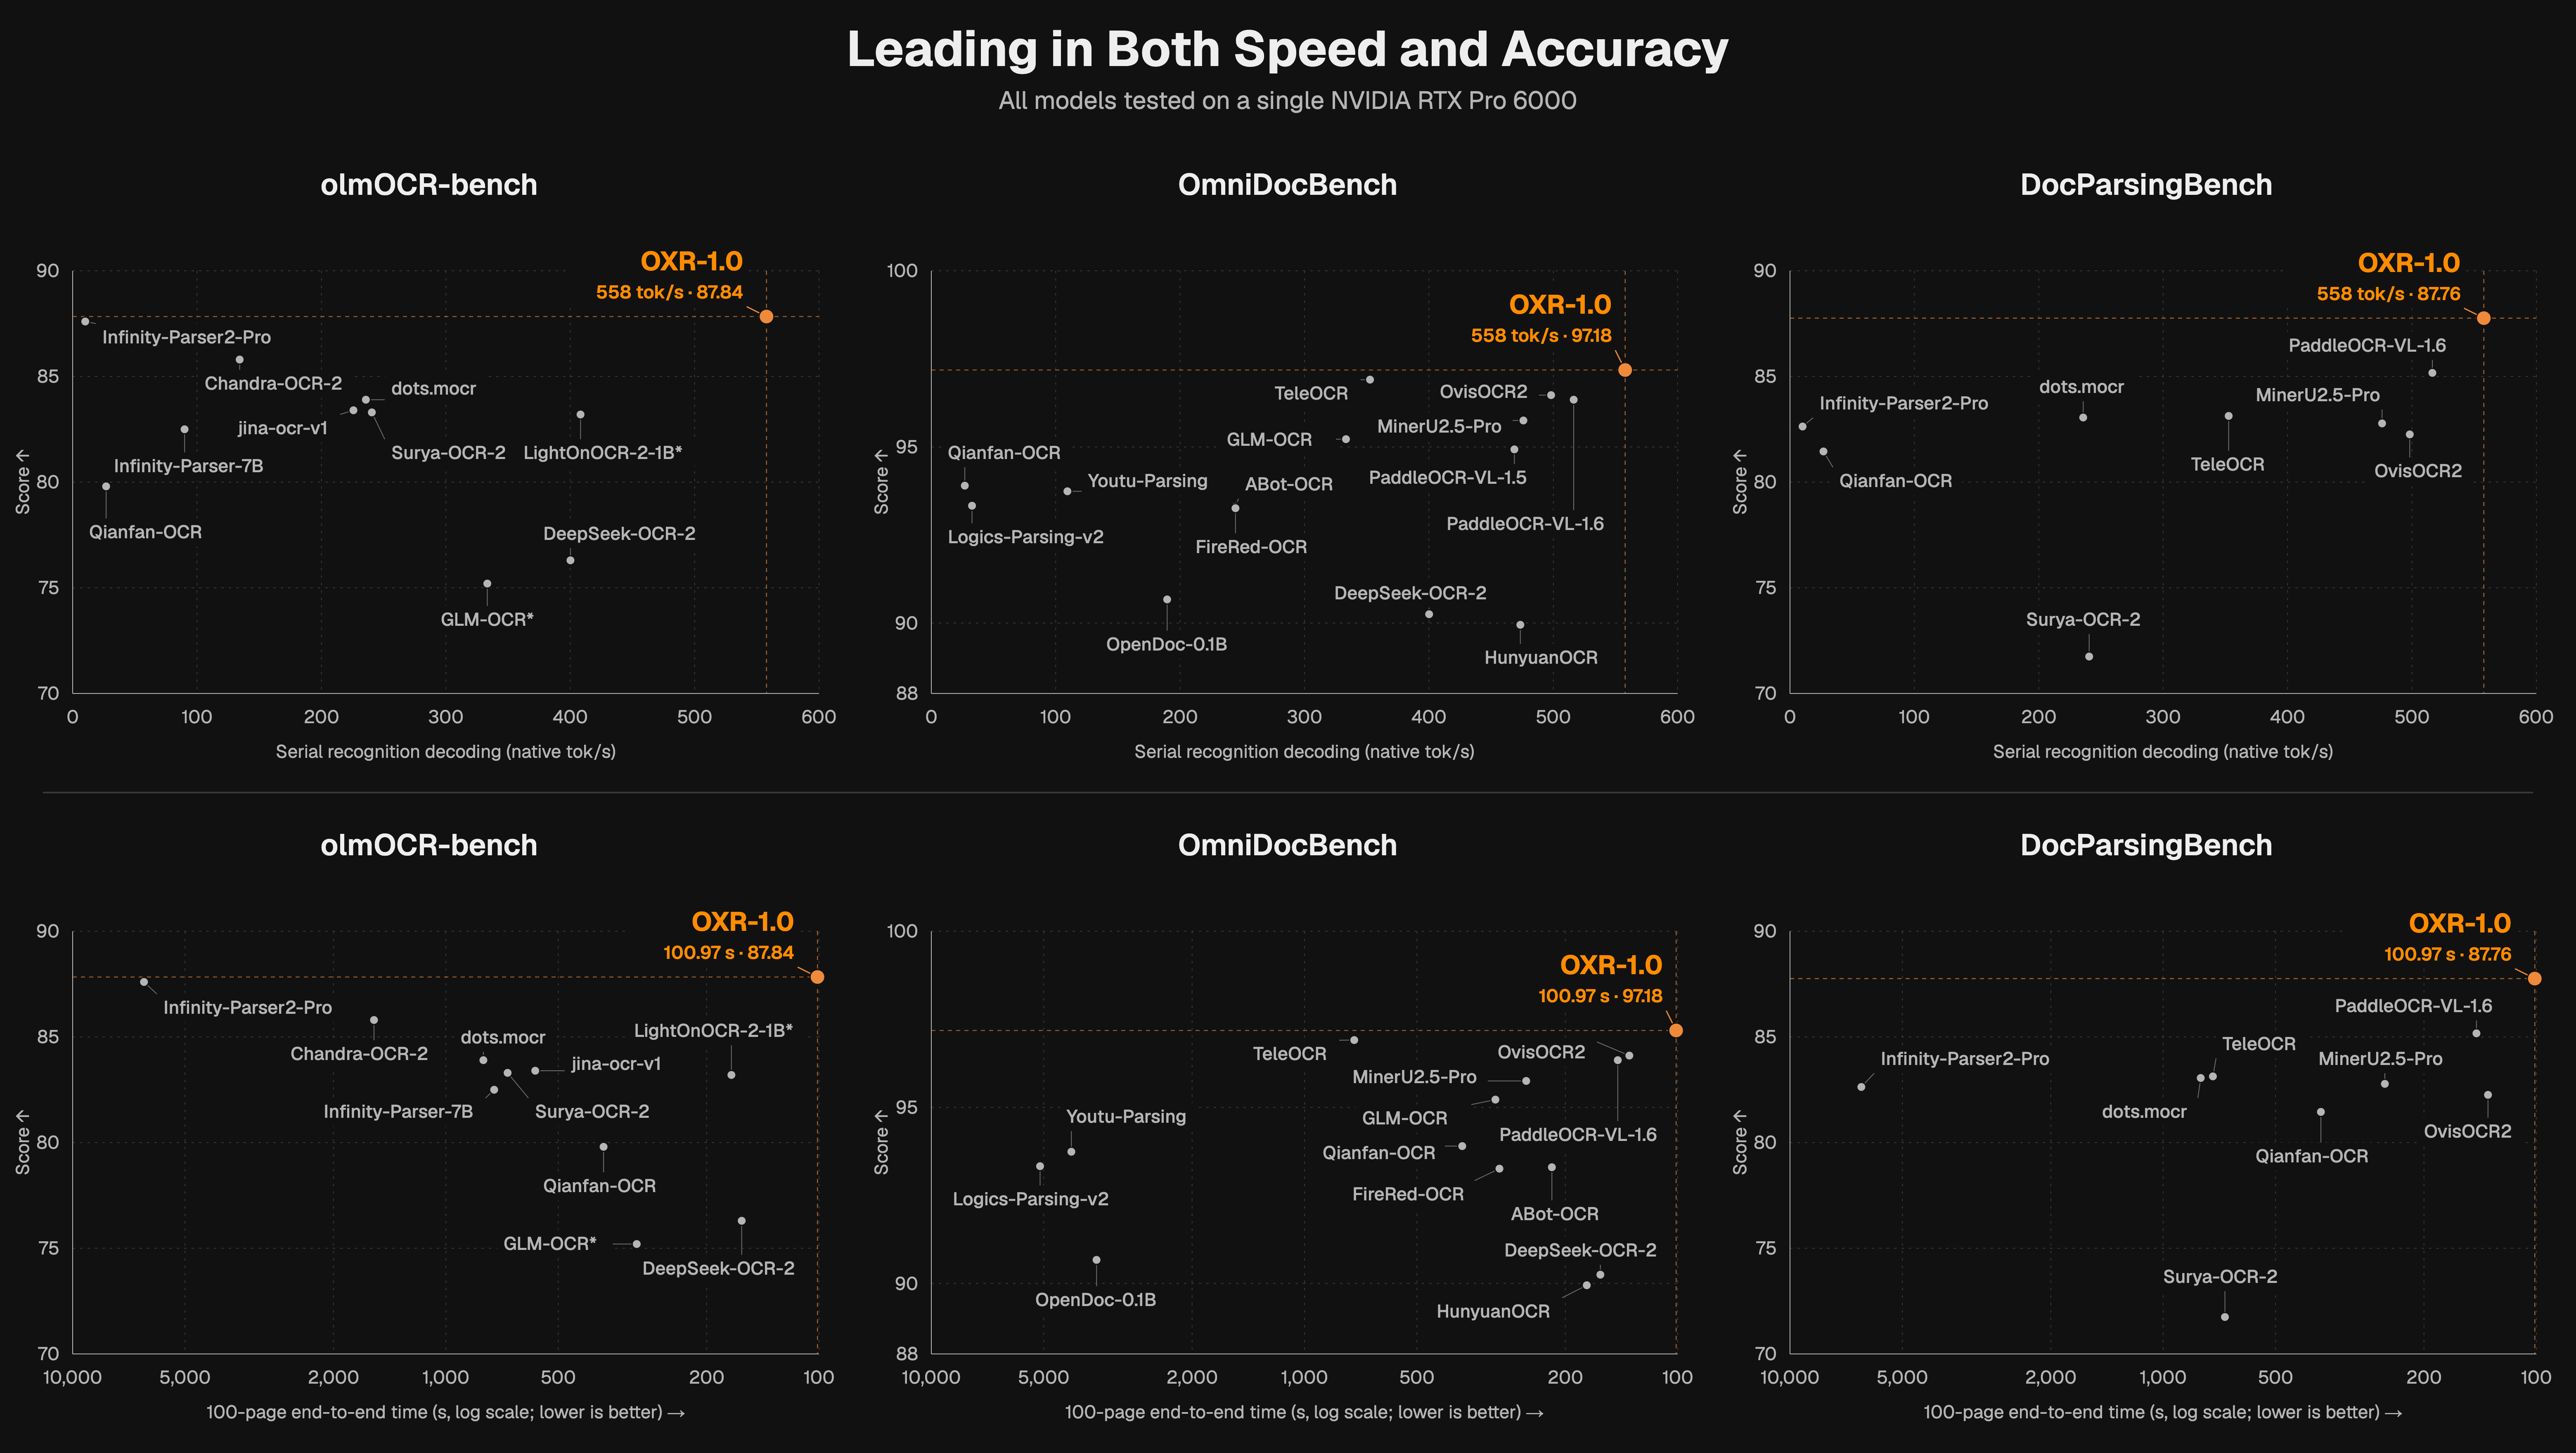
- With only 1.3B parameters, OXR ranks 🏆#1 among open-source document parsing models in speed tests on the RTX PRO 6000.
- OXR redesign its processing architecture at the task level to improve parsing speed while maintaining accuracy.
- See docs/benchmark.md